How to Create an AI Using Python: 7 Practical Steps
By Zari M'Bale · October 19, 2026
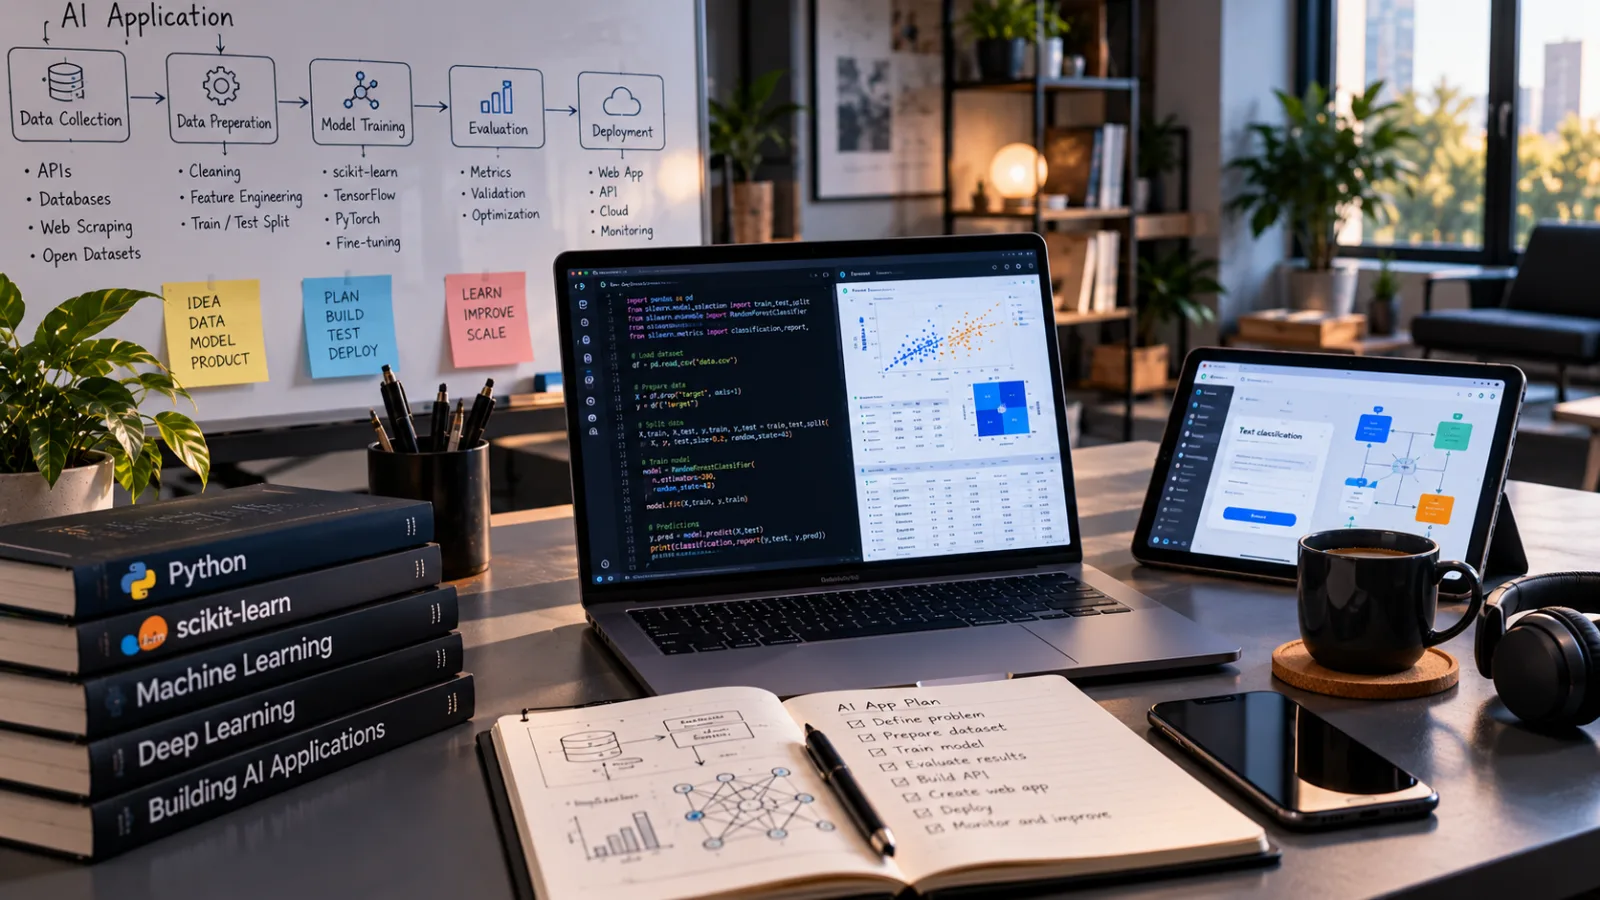
Table of contents
- 1. Define the AI You Want to Build
- 2. Prepare Your Python Environment
- 3. Collect and Prepare the Data
- 4. Train Your First AI Model
- 5. Evaluate and Improve the Model
- 6. Integrate Existing AI Models
- 7. Turn the Model Into a Real Application
- 8. Follow a Practical Learning Roadmap
- 9. Avoid Common AI Development Mistakes
- 10. Build AI Responsibly
- Frequently Asked Questions
Artificial intelligence can classify customer messages, recognise patterns in business data, analyse documents, predict trends and automate repetitive tasks.
Python makes these applications accessible because it provides a large ecosystem of tools for machine learning, natural language processing, computer vision and deep learning.
You do not need to develop an advanced neural network from scratch to create a useful AI application.
You can begin with a small model that learns from examples, evaluate its predictions and gradually expand its capabilities.
You can also integrate existing AI models into your own software when training a model yourself would require unnecessary time and resources.
Learning how to create an AI using Python involves understanding the problem, preparing reliable data, choosing suitable tools, training or integrating a model, testing its performance and making it available to users.
This guide covers the entire process, from the first project idea to deployment and ongoing maintenance.
1. Define the AI You Want to Build
Before choosing a Python library, determine what your artificial intelligence application should accomplish.
The problem defines the data you need, the type of model you should consider and the criteria you will use to evaluate the result.
Artificial intelligence covers several approaches.
Some applications follow predefined rules, while others learn from examples or use pretrained models to generate content and interpret complex information.
For a first project, choose a problem with a clear input and output.
This makes it easier to understand whether the application works and what needs to improve.
Choose a Practical Problem
Imagine that a company receives hundreds of customer messages every day.
Employees must identify complaints, billing questions, technical problems and general enquiries before forwarding each message to the appropriate department.
You could create an AI application that classifies these messages automatically.
The application would receive a message, analyse its content and predict the most appropriate category.
An employee could review the result before the message enters the support workflow.
This is a manageable starting point because the categories can be defined in advance and the predictions can be evaluated against known answers.
Other potential projects include:
Email classification: Identify spam, sales enquiries, complaints and important messages.
Sentiment analysis: Estimate whether a customer review expresses positive, negative or neutral sentiment.
Sales forecasting: Estimate future sales using historical transaction records.
Document classification: Categorise invoices, contracts, reports and other business documents.
Image recognition: Identify objects or assign images to predefined categories.
Recommendation systems: Suggest products, articles or courses based on relevant information about user interests.
Anomaly detection: Identify unusual transactions, unexpected server activity or abnormal equipment readings.
Select a problem that has practical value and data you can access legitimately.
Building an AI to classify a limited number of customer enquiries is a more manageable first project than attempting to create a general purpose conversational assistant.
Understand the Main Approaches
Rule based systems follow instructions created by a developer.
For example, a simple application might flag every message containing a particular billing term.
This can work when the conditions are predictable, but it struggles when users express the same idea in different ways.
Machine learning identifies patterns in examples.
Instead of manually defining every possible situation, you provide training data that helps the model learn relationships between inputs and expected results.
Deep learning uses neural networks with multiple processing layers to learn complex patterns.
It supports applications such as speech recognition, image processing and advanced language understanding.
Generative AI produces new content, including text, images, summaries and other outputs.
Developers can integrate existing generative models into applications through supported services or run suitable models on their own infrastructure.
These approaches can overlap.
A generative AI application may rely on a deep learning model, while a conventional machine learning application may focus on a specific prediction task.
Your first objective is not to use the most advanced technology available.
It is to choose the simplest appropriate approach for the problem you want to solve.
Define the Expected Results
Before development begins, establish what success means.
For a customer message classifier, the requirements might include the following:
Input: A text message submitted by a customer.
Output: A predicted category such as billing, technical support or general enquiry.
Evaluation: The proportion of correct predictions and the types of mistakes the model makes.
 4.7VPN
ExpressVPN
4.7ExpressVPN delivers fast Lightway speeds, audited no logs privacy, and reliable streaming access across new Basic, Advanced, and Pro plans.
- Very fast Lightway protocol speeds
- RAM only TrustedServer infrastructure design
- Pricier than most mainstream competitors
- No permanent free plan available
Business requirement: Uncertain or sensitive cases must be reviewed by an employee.
These requirements give the project a measurable direction.
They also help prevent unnecessary development work before you have confirmed that the underlying model can solve the problem.
2. Prepare Your Python Environment
Python is widely used in artificial intelligence because its ecosystem supports data preparation, statistical analysis, traditional machine learning and deep learning.
Your development environment should provide a way to write and test Python applications, manage dependencies and inspect results.
You do not need expensive equipment or a complicated infrastructure for every beginner project.
Select Your Development Tools
Several established tools can support your work.
Visual Studio Code is a development editor with Python support.
It is useful when you want to create an application containing multiple files, manage a project folder and eventually deploy the application.
JupyterLab provides an interactive notebook environment.
You can execute individual sections of a project, examine datasets and inspect model results as you work.
Google Colab provides browser based notebooks that let you experiment without configuring an entire local development environment.
Depending on the available service and account limits, it can also provide access to accelerated computing resources.
Anaconda provides a Python distribution and environment management tools commonly used in data science.
You do not need to install every option.
Visual Studio Code is a practical choice for developing a conventional application, while JupyterLab and Google Colab are useful for experimentation and learning.
Install the Required Libraries
After installing a compatible Python version, select the libraries needed for your project.
For a basic text classification application, three useful choices are scikit learn, Pandas and Joblib.
Scikit learn provides algorithms for classification, regression, clustering and model evaluation.
It also includes tools for transforming text into numerical features.
Pandas helps you load, organise, filter and analyse structured data.
It is especially useful when working with spreadsheets, CSV files and datasets containing thousands of records.
Joblib helps save trained models and load them later, allowing an application to reuse a model without repeating the entire training process.
For other projects, you may need different tools.
PyTorch and TensorFlow support deep learning, while Hugging Face Transformers provides access to numerous pretrained language models.
Install only the dependencies required by the project.
Keeping the initial environment manageable makes troubleshooting easier and reduces unnecessary complexity.
Organise the Project
A well organised project is easier to understand, test and maintain.
Keep your training process separate from the application responsible for making predictions.
Store datasets in clearly named locations, record important model settings and document how the project should be executed.
Use a virtual environment to isolate the project's Python dependencies from those of other applications.
This helps prevent conflicting package versions and makes it easier to reproduce the development environment.
You should also establish basic security practices from the beginning.
Keep passwords and API credentials outside the application source files, restrict access to confidential datasets and avoid including sensitive customer information in unrestricted logs.
These decisions may seem minor during a small experiment, but they become increasingly important when the project grows or moves into a production environment.
3. Collect and Prepare the Data
Machine learning models depend on the quality and relevance of their training data.
A sophisticated algorithm cannot reliably compensate for examples that are incorrect, inconsistent or unrelated to the situations the application will encounter.
Data preparation therefore deserves significant attention before model training begins.
Gather Representative Examples
For a customer message classifier, you need messages associated with known categories.
Consider these examples:
A customer cannot access an account.
The expected category is technical support.
A customer reports an incorrect invoice amount.
The expected category is billing.
A customer requests information about available services.
The expected category is general enquiry.
A customer reports that a document upload fails.
The expected category is technical support.
A customer questions a duplicate charge.
The expected category is billing.
These examples demonstrate the relationship between the information provided to the model and the expected prediction.
A real application needs a larger and more representative collection of messages.
Customers may use abbreviations, spelling mistakes, regional expressions or lengthy descriptions.
Some messages may contain multiple problems, while others may be too vague to classify confidently.
Your dataset should reflect these variations.
For business applications, suitable data might come from authorised historical records, carefully reviewed internal examples or publicly available datasets whose licences permit the intended use.
Label the Dataset Correctly
In supervised machine learning, labels identify the correct answer associated with each training example.
For example, a collection of messages may contain labels for billing, technical support and general enquiries.
During training, the model uses these examples to learn patterns associated with each category.
Inconsistent labels create problems.
If several messages about duplicate payments are labelled as technical support while similar messages are labelled as billing, the model receives conflicting information.
Define each category clearly before labelling a large dataset.
Establish rules for ambiguous cases, messages containing multiple issues and enquiries that do not fit the existing categories.
Where possible, review a sample of labelled records and correct inconsistencies before training.
Divide the Data Properly
You need to evaluate the model using examples that were not used to train it.
A common approach is to divide the dataset into three groups.
The training set provides the examples from which the model learns.
The validation set helps you compare different configurations and make development decisions.
The test set provides a final evaluation of the selected model.
For a small learning project, you can begin with separate training and test sets.
As the project becomes more sophisticated, a validation set helps you compare alternatives without repeatedly relying on the final test results.
Make sure that the test set reflects the situations the application will encounter in practice.
For text classification, preserving the representation of each category can be helpful, particularly when some categories contain relatively few examples.
Avoid allowing duplicate or nearly identical records to appear in both training and test sets.
This can produce misleading results because the model may effectively encounter familiar examples during evaluation.
Protect Private Information
Business data may contain names, email addresses, account details, financial records or confidential documents.
Before using this information, confirm that you have the necessary authorisation and that your processing arrangements meet the relevant privacy and security requirements.
Remove personal information that is not required for the task.
Limit access to raw datasets and establish appropriate retention practices.
If an external AI provider will process the data, review the provider's terms, privacy controls and data handling arrangements before submitting confidential information.
Responsible data management should be part of the project from the beginning, rather than an additional task after the model has been built.
4. Train Your First AI Model
Once your dataset is ready, you can train a model to recognise patterns and produce predictions.
For a beginner, a traditional machine learning classifier is a useful starting point.
It teaches the essential development process without requiring the infrastructure or training resources associated with large neural networks.
Understand Text Classification
A computer does not automatically understand a sentence in the same way a person does.
A conventional text classification model needs a numerical representation of the text before it can learn relationships between messages and categories.
One approach is TF IDF, which represents text using numerical features based on the words appearing in the documents and how informative those words are across the dataset.
For example, words that appear in many unrelated messages may provide less information than terms strongly associated with a particular category.
A classification algorithm then learns how these features relate to the known labels.
Scikit learn provides a convenient way to combine text processing and classification into one reusable pipeline.
The pipeline can learn the text representation from the training data and apply the same transformation when processing new messages.
Choose a Suitable Algorithm
Logistic regression is a reasonable first choice for many text classification problems.
Despite its name, it is widely used for classification and can perform well with sparse text features.
Other options include naive Bayes classifiers and linear support vector machines.
Each has different characteristics, and the best choice depends on the dataset and the problem.
You do not need to understand every mathematical detail before training your first model.
However, you should understand the role of each component and how the training process uses labelled examples.
The objective is to build a baseline model that you can evaluate and improve.
Train the Model
In your development environment, organise the prepared messages and their corresponding categories.
Select a training set, choose a suitable text representation and configure the classification algorithm.
The training process uses the examples to estimate the relationships between the numerical features and the expected categories.
After training, the model can process messages it has not previously encountered and produce predicted categories.
For instance, a customer might write that a payment was deducted twice.
The model examines the message and estimates whether it belongs to billing, technical support or another available category.
The prediction is not guaranteed to be correct.
The model has learned statistical patterns from its training data, and its reliability depends on how well those examples represent real situations.
Save the Trained Model
After training and evaluating the model, save it so that the application can reuse it later.
This avoids repeating the training process whenever a user wants to make a prediction.
The saved model should be associated with useful information about its development, including the training dataset, model configuration, evaluation results and relevant software dependencies.
Treat model files as trusted software assets.
Python serialisation formats such as Joblib and Pickle can execute code during loading, so loading a file from an untrusted source can introduce serious security risks.
A saved model is one component of the application.
The surrounding software must still validate incoming data, handle errors and protect sensitive information.
5. Evaluate and Improve the Model
A model that produces predictions is not necessarily a model that performs well.
You need to evaluate its results, identify weaknesses and make improvements based on evidence.
Understand the Main Metrics
Accuracy measures the proportion of predictions that are correct.
It is useful when the categories are reasonably balanced and different types of mistakes have similar consequences.
ExpressVPN
ExpressVPN delivers fast Lightway speeds, audited no logs privacy, and reliable streaming access across new Basic, Advanced, and Pro plans.
- Very fast Lightway protocol speeds
- RAM only TrustedServer infrastructure design
- Pricier than most mainstream competitors
- No permanent free plan available
Precision measures how often predictions assigned to a particular category are correct.
For example, high precision for billing means that messages classified as billing are usually genuine billing enquiries.
Recall measures how many of the actual examples belonging to a category the model successfully identifies.
High recall for technical support means that relatively few genuine technical problems are missed.
F1 score combines precision and recall into a single measure.
It is useful when you need to consider both types of error.
Imagine that a company receives far more general enquiries than technical support requests.
A model that classifies nearly every message as a general enquiry might achieve reasonable overall accuracy while failing to identify important technical problems.
Review the results for each category instead of relying on one overall score.
Examine Incorrect Predictions
One of the most valuable activities in AI development is reviewing the model's mistakes.
Suppose a customer writes, "I cannot use the service because my payment failed."
Depending on the company's classification policy, this could be a billing issue, a technical issue or a combination of both.
The model cannot reliably resolve an unclear classification policy simply by receiving more examples.
You may need to define how such cases should be handled before adjusting the algorithm.
Other mistakes may result from insufficient training data, inconsistent labels or expressions that are poorly represented in the dataset.
Look for recurring error patterns.
If the model repeatedly confuses two categories, investigate whether the categories overlap or whether additional representative examples could help.
Expand the Dataset
A larger dataset can improve performance when the additional examples provide useful information.
Collect examples that represent different writing styles, customer situations and product areas.
Ensure that important categories have sufficient representation and that labels remain consistent.
Do not assume that adding large quantities of duplicate information will automatically improve the model.
Repeated examples can distort learning and produce an unrealistic impression of performance.
The goal is to improve the quality and coverage of the data, not simply to increase its size.
Compare Different Models
After establishing a baseline, compare suitable algorithms using consistent evaluation procedures.
You might compare logistic regression with a naive Bayes classifier or a linear support vector classifier.
For more complex language tasks, you could investigate pretrained transformer models.
Use the same data preparation rules and comparable evaluation sets when assessing alternatives.
Otherwise, differences in results may reflect changes in the data rather than improvements in the algorithm.
For larger projects, cross validation can help estimate how consistently a model performs across different portions of the available dataset.
Keep records of the configurations you test and the results they produce.
This makes it easier to understand which changes genuinely improve the application.
6. Integrate Existing AI Models
Training a model from scratch is not always the most practical way to create an AI application.
Many developers use pretrained models that have already learned patterns from substantial datasets.
Depending on the model and its licence, you may be able to use it directly, adapt it to a specific task or access it through a provider's API.
This approach is particularly useful for language generation, summarisation, question answering and other tasks that can require extensive training resources.
Use an AI API
An application programming interface allows your Python application to communicate with an external AI service.
For example, a customer support application could send an authorised enquiry to a language model and request a concise summary.
The application could display the summary alongside the original message for an employee to review.
OpenAI, Anthropic and Google provide AI services with capabilities that may support these types of applications.
Available models, features, prices and usage conditions vary by provider.
Before choosing a service, assess the quality of its outputs, expected request volume, response time, cost and privacy requirements.
External APIs can reduce the infrastructure needed to run advanced models, but they introduce dependencies on network availability, provider policies and service pricing.
Protect API credentials, handle failed requests and avoid exposing confidential information unnecessarily.
You should also review the provider's current documentation before implementing an integration because capabilities and interfaces can change.
Explore Open Models
Some pretrained models can be downloaded and operated on your own infrastructure, subject to their licences and technical requirements.
Hugging Face Transformers provides access to a broad range of models for text classification, summarisation, language generation and other tasks.
Running a model locally can provide greater control over data processing and deployment.
However, it requires suitable hardware, software compatibility, security controls and maintenance.
A small model may run comfortably on a standard computer, while a larger model may require substantial memory or specialised hardware.
Evaluate the full operational requirements before deciding to host a model yourself.
Fine Tune a Pretrained Model
Fine tuning involves further training an existing model on examples related to a specific task.
For instance, a company might adapt a suitable text model to recognise technical support requests involving its own products.
Fine tuning can improve performance for specialised tasks when the training data is relevant and the evaluation process is sound.
It does not guarantee that the model will become accurate, and it does not automatically eliminate errors or inappropriate outputs.
You need suitable examples, adequate computing resources and a reliable way to compare the adapted model against the original.
For some applications, carefully prepared instructions, retrieval of relevant documents or a conventional classifier may provide sufficient results without fine tuning.
Select Tools According to the Task
Different tools support different parts of the development process.
Scikit learn is suitable for traditional machine learning, including classification and regression.
PyTorch provides a framework for building and training neural networks.
TensorFlow supports deep learning development and deployment.
Hugging Face Transformers provides access to many pretrained transformer models.
Streamlit helps developers create interactive web applications using Python.
FastAPI allows developers to expose application functionality through APIs.
Choose tools according to your requirements, experience, infrastructure and budget.
You can build a useful AI application without adopting every framework in the ecosystem.
7. Turn the Model Into a Real Application
A trained model becomes more useful when people can access it through a practical interface or an existing business workflow.
The appropriate delivery method depends on the audience and the consequences of its predictions.
An internal experiment may only require a local application.
A service used by several departments may need a web interface, authentication, monitoring and a reliable deployment environment.
Create a User Interface
Streamlit can help you create a simple interface for a Python application.
For the customer message classifier, the interface could provide a text field where an employee enters a message, a control to request a prediction and a result area displaying the suggested category.
The interface should make the result understandable and allow users to correct mistakes.
Where the model is uncertain or the consequences of an incorrect prediction are significant, the application should request human review rather than automatically treating the prediction as a confirmed fact.
For more complex applications, FastAPI can expose the model through an API.
A website, internal dashboard or customer management system can then communicate with the AI service.
Keeping the model separate from the user interface makes it easier to update the model without redesigning the entire application.
Deploy the Application
A small project can run on a local computer or an internal server.
Applications intended for wider use may require cloud hosting or a containerised deployment.
Docker can package an application and its dependencies into a container, helping maintain consistency between development and deployment environments.
Cloud platforms can provide the infrastructure required to run an application, store data and manage traffic.
The appropriate platform depends on the workload, security requirements and budget.
Before deployment, verify that the environment has sufficient memory, processing capacity and network access.
If the model needs a GPU, confirm that the selected platform provides compatible hardware and drivers.
Also plan for application updates, dependency security fixes, backups and recovery procedures.
Secure the Application
AI applications can process sensitive information and interact with other business systems.
Security must therefore extend beyond the model itself.
Restrict access to authorised users.
Protect credentials and stored data.
Validate incoming requests and limit the information written to logs.
If the application processes customer messages, ensure that its data handling practices meet the organisation's requirements.
For systems that use external models, consider what happens if the provider becomes unavailable, returns an unexpected response or changes its service.
A dependable application needs clear error handling and a controlled way to recover from failures.
Maintain the Model After Launch
Model deployment is not the final stage of development.
Customer behaviour, products, terminology and business processes can change over time.
A model that performed well during testing may become less effective when the incoming data no longer resembles its training examples.
Monitor appropriate performance indicators, including prediction latency, application errors and the distribution of predicted categories.
Where permitted, collect reviewed outcomes to determine whether predictions remain useful.
Protect personal information and establish clear rules for data retention.
Retrain or replace the model when evidence shows that an update is needed.
Evaluate the new version before making it available to users, and retain a way to restore a previous version if the update causes problems.
8. Follow a Practical Learning Roadmap
If you are new to Python and artificial intelligence, a structured development plan can help you progress from basic programming to a working application.
Step 1: Learn Python fundamentals. Understand variables, lists, dictionaries, functions, loops, file handling, imports and exception handling.
These concepts make machine learning projects easier to follow.
Step 2: Learn basic data analysis. Practise working with datasets, identifying missing values, examining distributions and correcting inconsistent information.
Pandas is useful for these tasks.
Step 3: Choose a small problem. Select a task with a clear input and output, such as classifying customer enquiries or predicting a category from structured information.
Step 4: Prepare the dataset. Collect authorised examples, define the labels and check for inconsistencies.
Keep separate data for training and evaluation.
Step 5: Train a baseline model. Use scikit learn to train a simple classifier or another suitable model.
Focus on understanding the purpose of each component.
Step 6: Evaluate the results. Review accuracy, precision, recall and other relevant metrics.
Investigate incorrect predictions and identify areas that need improvement.
Step 7: Improve the solution. Add representative examples, refine the labels and compare suitable algorithms.
Record the results of each experiment.
Step 8: Build an interface. Use Streamlit for a simple web interface or FastAPI when other applications need to access the model.
Step 9: Deploy securely. Prepare the environment, manage dependencies, restrict access and test the application under realistic conditions.
Step 10: Monitor performance. Review errors, gather authorised feedback and evaluate updates before releasing them.
Each stage produces a practical result.
By the end, you will have developed an application that demonstrates data preparation, model training, evaluation and deployment.
You can then expand the project with additional categories, a larger dataset, a more advanced model or integration with an existing business system.
9. Avoid Common AI Development Mistakes
A successful project depends on sound decisions throughout development.
Beginners often focus too heavily on choosing advanced algorithms and overlook the quality of the data, the evaluation process or the needs of the people who will use the application.
Starting With an Oversized Model
Large language models and deep neural networks can be powerful, but they may introduce unnecessary complexity, infrastructure requirements and costs.
Begin with a baseline model and establish how well it performs.
Consider more advanced approaches when you have identified limitations that justify the additional effort.
Training With Poor Data
Incorrect labels, missing information and unrepresentative examples can produce unreliable predictions.
Review the dataset before training and establish consistent labelling rules.
Collect examples that represent the situations the model will encounter after deployment.
Ignoring Model Errors
A single accuracy score cannot explain every weakness.
Review mistakes by category and examine their practical consequences.
A model that performs adequately on general enquiries may still fail on the technical problems that matter most to your organisation.
Overlooking Data Leakage
Data leakage occurs when information that would not be available during real prediction influences training or evaluation.
For example, nearly identical records appearing in both the training and test sets can produce misleading results.
Data preprocessing must also be fitted using training data only.
A correctly configured scikit learn pipeline can help maintain this separation, provided the data preparation and evaluation process are designed properly.
ExpressVPN
ExpressVPN delivers fast Lightway speeds, audited no logs privacy, and reliable streaming access across new Basic, Advanced, and Pro plans.
- Very fast Lightway protocol speeds
- RAM only TrustedServer infrastructure design
- Pricier than most mainstream competitors
- No permanent free plan available
Neglecting Privacy and Security
AI applications may process confidential records or communicate with external services.
Review data permissions, restrict access, protect credentials and understand the implications of sending information to third party providers.
Do not assume that a model file, external response or generated summary is automatically trustworthy.
Skipping Maintenance
A model can become less effective as the data changes.
Establish a process for monitoring performance, reviewing errors and evaluating new versions.
Record model versions and retain the information needed to reproduce important experiments.
Maintenance should be part of the original project plan, not an afterthought once the application is in use.
10. Build AI Responsibly
An AI application should be evaluated according to both its technical performance and its effect on the people who rely on it.
A classifier used to suggest a support department has different risks from a model used to make financial, employment or medical decisions.
Define which tasks the model may perform independently, which require human approval and how users can challenge or correct an outcome.
The National Institute of Standards and Technology provides an AI Risk Management Framework that organisations can use to think systematically about risks throughout the AI lifecycle.
For practical development, this means documenting known limitations, evaluating failure scenarios, protecting sensitive information and establishing appropriate oversight.
You should also check the licence and usage conditions of the libraries, datasets and models included in your application.
Commercial use may be subject to restrictions or obligations that differ between projects.
A technically impressive model is not automatically suitable for every business purpose.
Reliability, transparency, security and appropriate human involvement are important parts of building a useful AI system.
Frequently Asked Questions
Can Beginners Create AI?
Yes.
Python libraries such as scikit learn allow beginners to train machine learning models without implementing every algorithm from scratch.
Start with a small problem and gradually expand your technical knowledge.
Is Python Required for AI?
No. Other programming languages and development platforms support artificial intelligence.
Python is popular because it offers an extensive ecosystem for data analysis, machine learning, deep learning and application development.
Can I Build AI Without a GPU?
Yes.
Many traditional machine learning models can be trained and used on a standard computer CPU.
A GPU becomes more useful for certain deep learning workloads and larger models, but it is not necessary for every project.
How Much Does AI Development Cost?
The cost depends on the complexity of the application, the data, the infrastructure and the chosen model.
A small local prototype may require little beyond your time and computer resources.
A production application may involve hosting, API usage, security, data preparation and maintenance.
Should I Train My Own Model?
Training your own model can be appropriate when you have suitable data and need a specialised solution.
For complex language or image tasks, using a pretrained model may be more practical.
Evaluate the available options against your technical and business requirements.
Which Python AI Library Is Best?
Scikit learn is an excellent starting point for traditional machine learning.
PyTorch and TensorFlow support deep learning, while Hugging Face Transformers provides access to many pretrained models.
The best choice depends on your task.
How Do I Test an AI Model?
Evaluate the model using examples that were not included in training.
Review relevant metrics, inspect incorrect predictions and test realistic scenarios.
For important applications, continue monitoring performance after deployment.
Can I Sell an AI Application?
Yes, provided that your application complies with the licences, service terms, privacy requirements and other obligations relevant to its components and intended use.
A commercial application also needs appropriate security, reliable infrastructure and a sustainable maintenance plan.